My Journey into Open AI: Exploring K2 Horizon
Background:
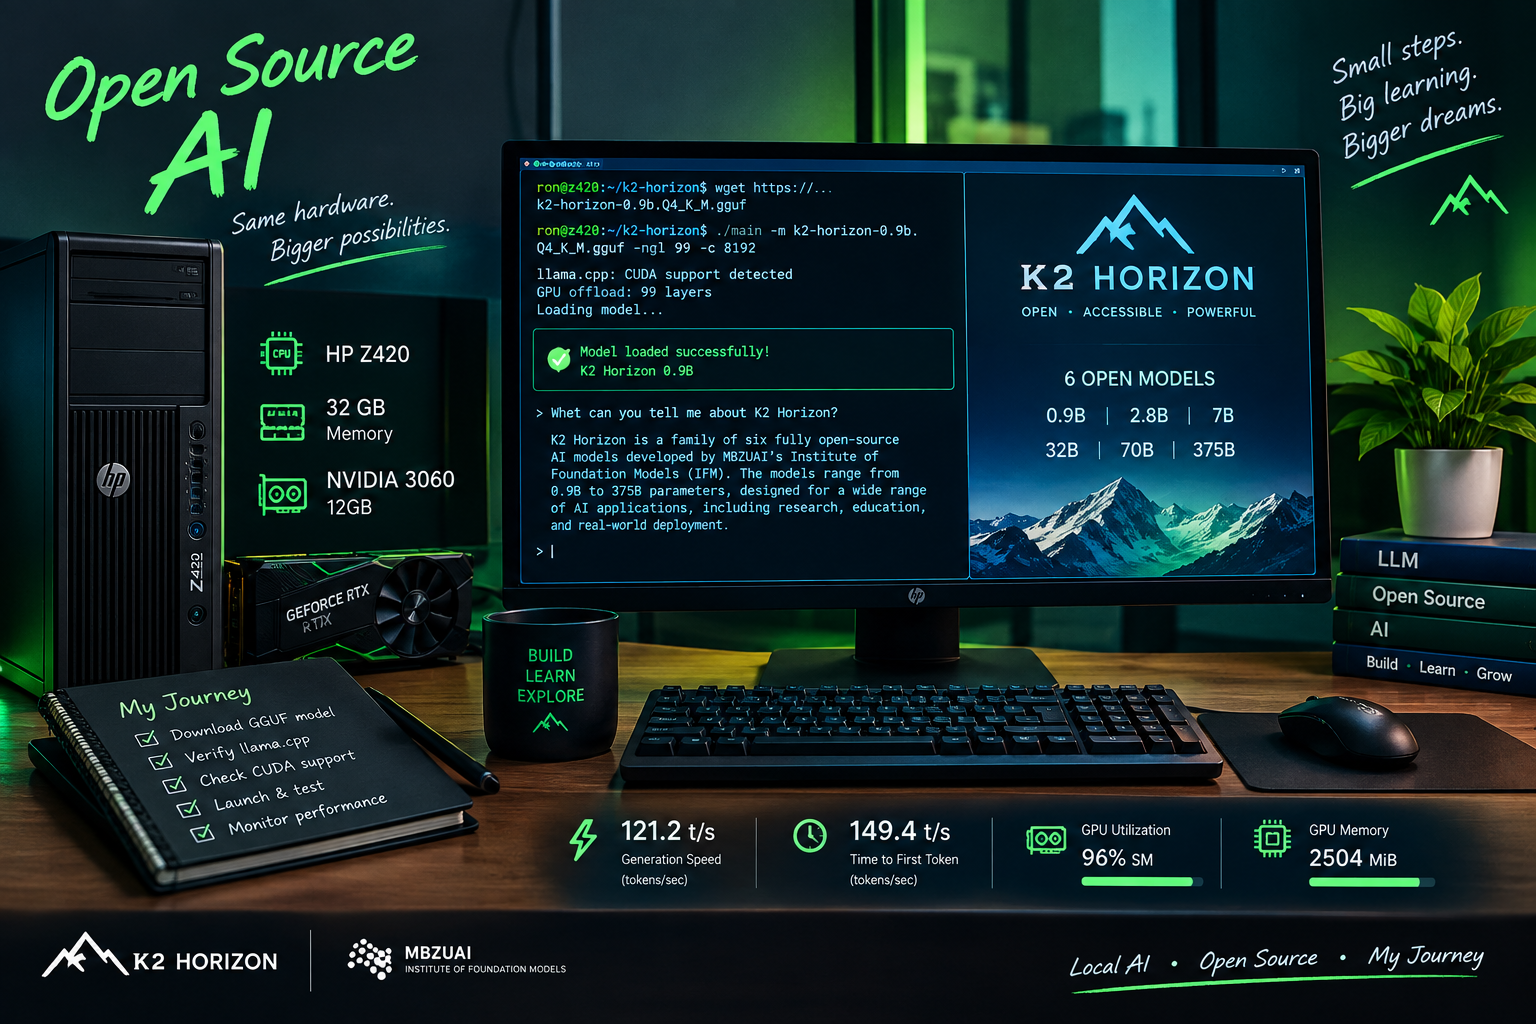
MBZUAI’s Institute of Foundation Models (IFM) has launched K2 Horizon, a family of six fully open AI models ranging from 0.9B to 375B parameters.
Goal:
Explore K2 Horizon and see how far I can go with open-source AI using hardware I already have.
Hardware:
HP Z420
32 GB Memory
Nvidia 3060 12GB
Installation & Testing:
1. Downloaded the GGUF model

2. Verified the llama.cpp build

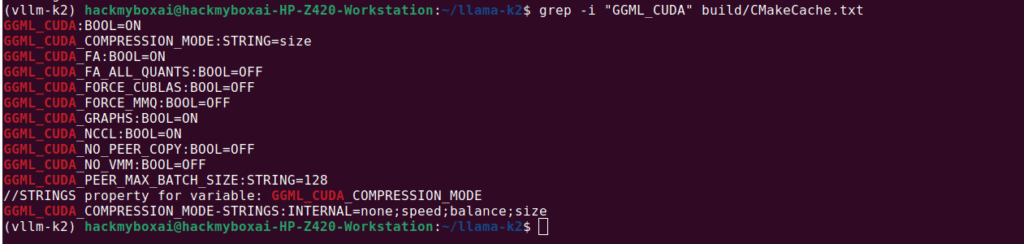
3. Checked CUDA support
4. Launched the model
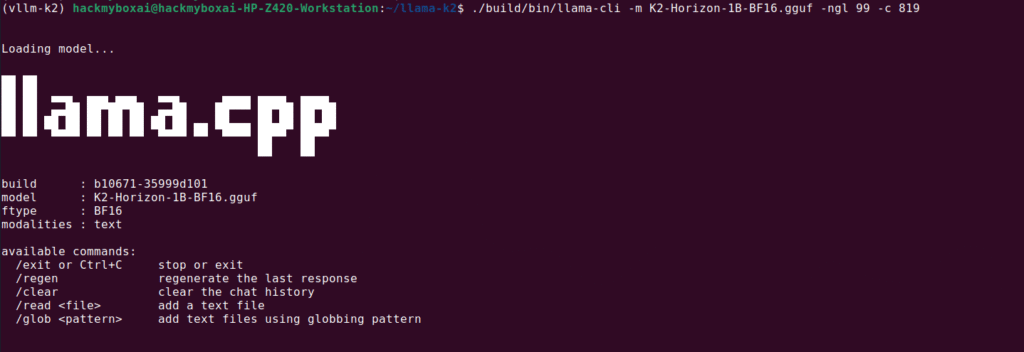
* ngl 99 -c 8192: This allows the model layers to be offloaded to the GPU.
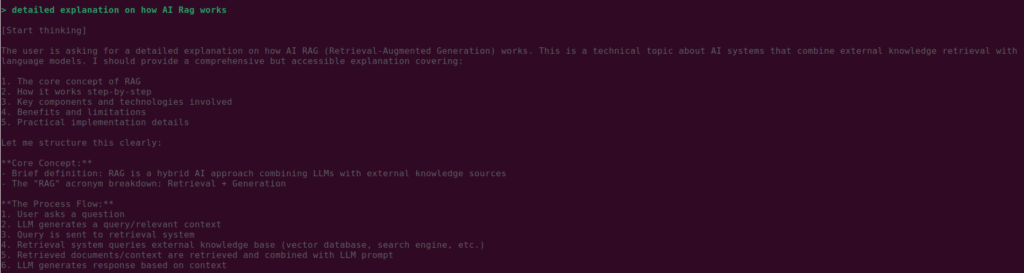
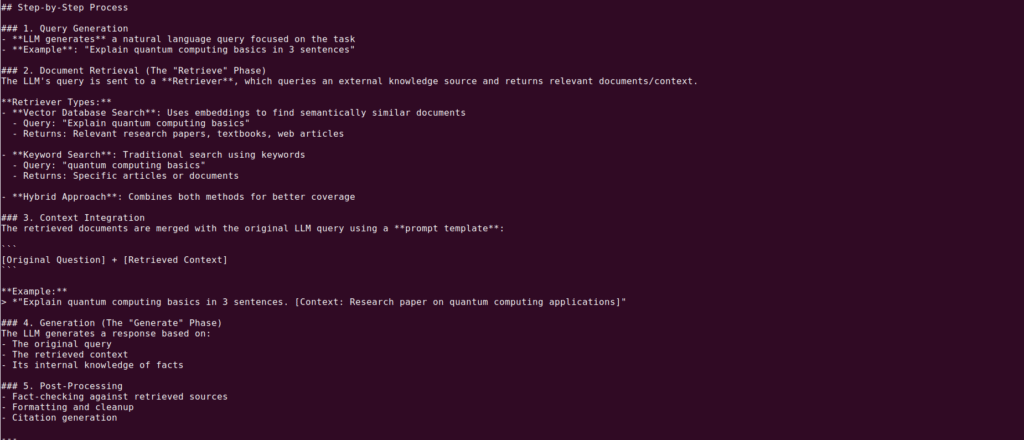
5. Testing
The model produced fast and coherent responses during testing.
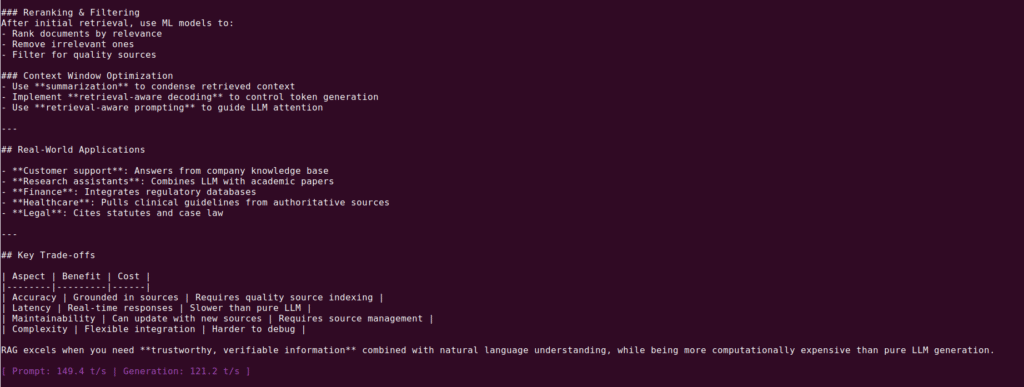
| Metric | Value | |
| Prompt | 149.4 t/s | Time-to-first-token speed. |
| Generation | 121.2 t/s | Token output speed. |
5. Monitoring
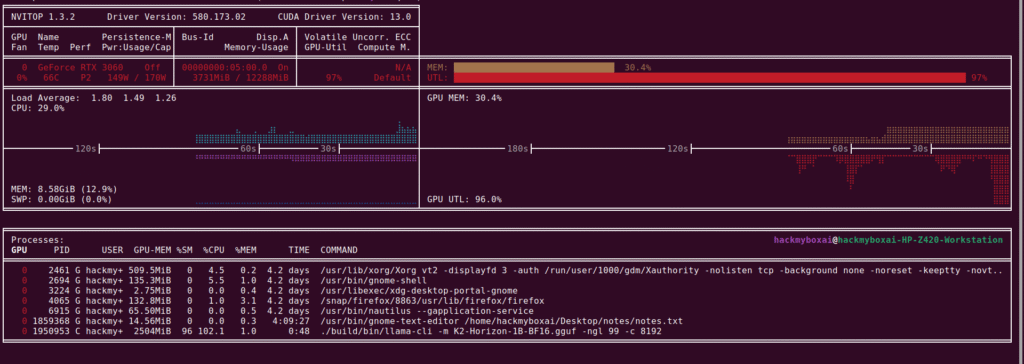
| Metric | Result | Description |
| GPU Memory | 2504 MiB | Model loaded into VRAM |
| GPU Utilization | 96% SM | GPU heavily utilized |
| CPU | 102.10% | CPU handling supporting tasks such as tokenization/IO |
| GPU Time | 0:48 | 48 seconds of GPU time |
| GPU Offload | -ngl 99 | All available model layers offloaded |
Summary
Starting my journey by exploring K2 Horizon a fully open family of AI models. Tested local inference with llama.cpp and CUDA achieving 121 tokens/sec generation speed.

Related Posts
Project RAG System
Jarvis AI Voice Assistant Project